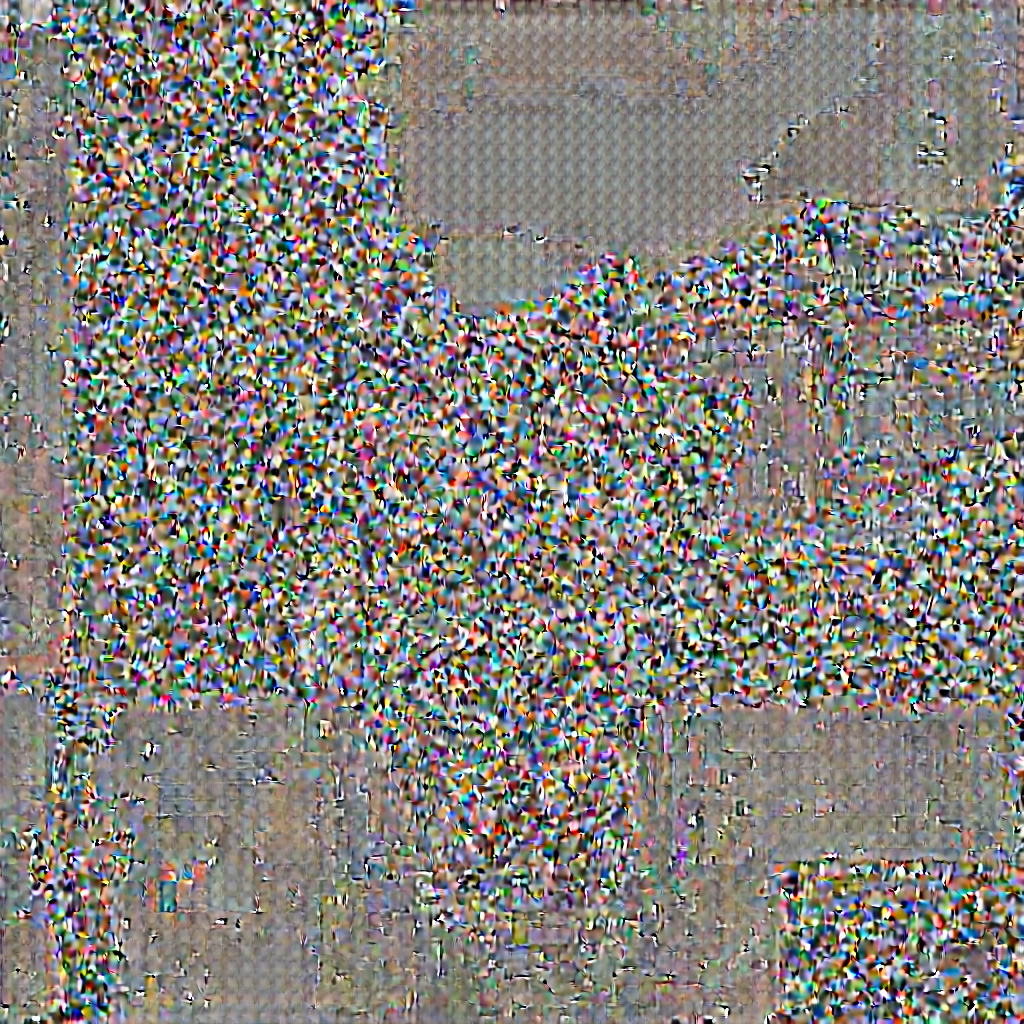Can image inversion help us spot AI-generated images?
I’m adapting a technique from image editing to investigate what an image reveals when you take it apart and put it back together.
The question
Does the extra information actually help?
My starting point was FakeInversion: using an image, its inverted noise and its reconstruction to detect whether it was AI-generated. I wanted to explore how that idea could be adapted to newer generator architectures.
That led me to FLUX and FireFlow, a technique developed for image editing. I’m using inversion to produce additional information for a classifier. The question is whether that information helps it make better decisions than it could from the original image alone.
This is my ongoing master’s thesis in Information Science at the University of Bergen. Below, I’m keeping track of the method, the results and the questions I still haven’t answered.
The method
One image, three inputs
BLIP-2 captioning · FLUX + FireFlow inversion
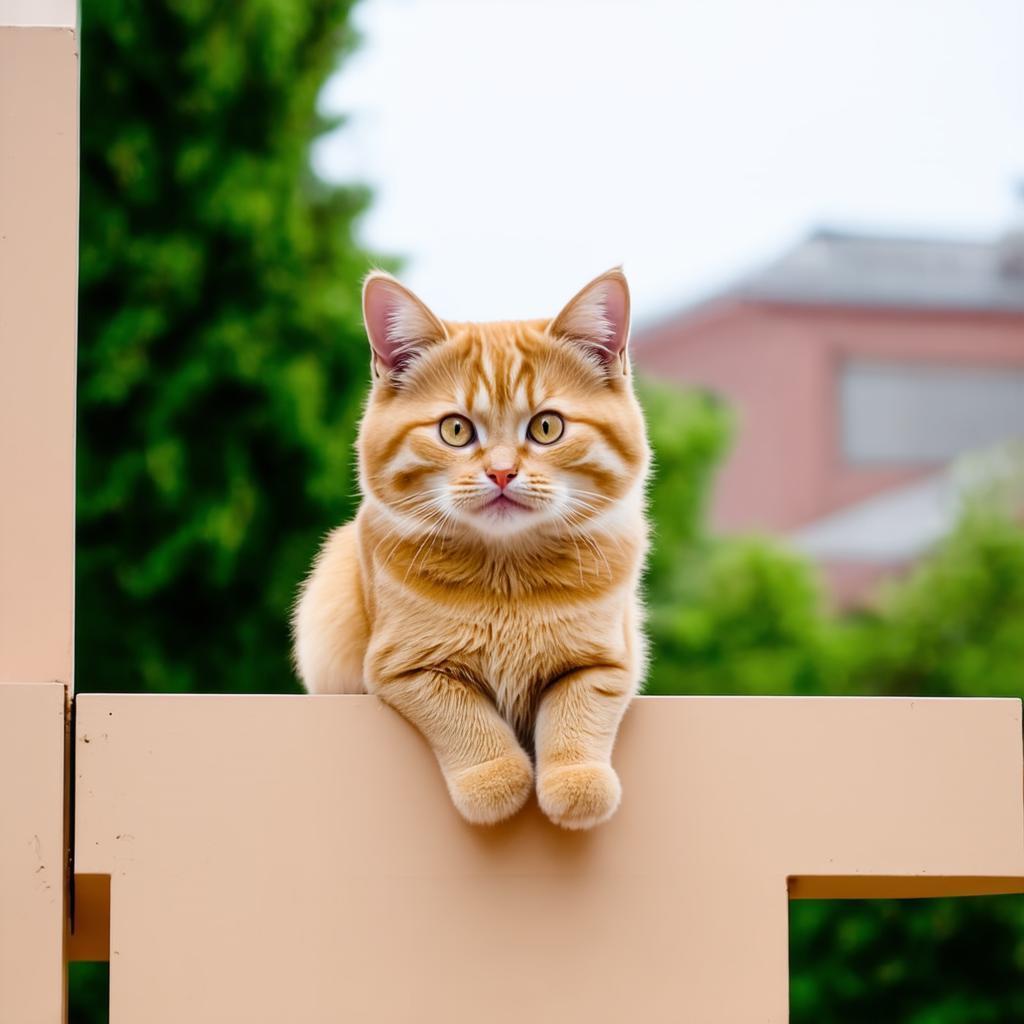
Original
Inverted noise
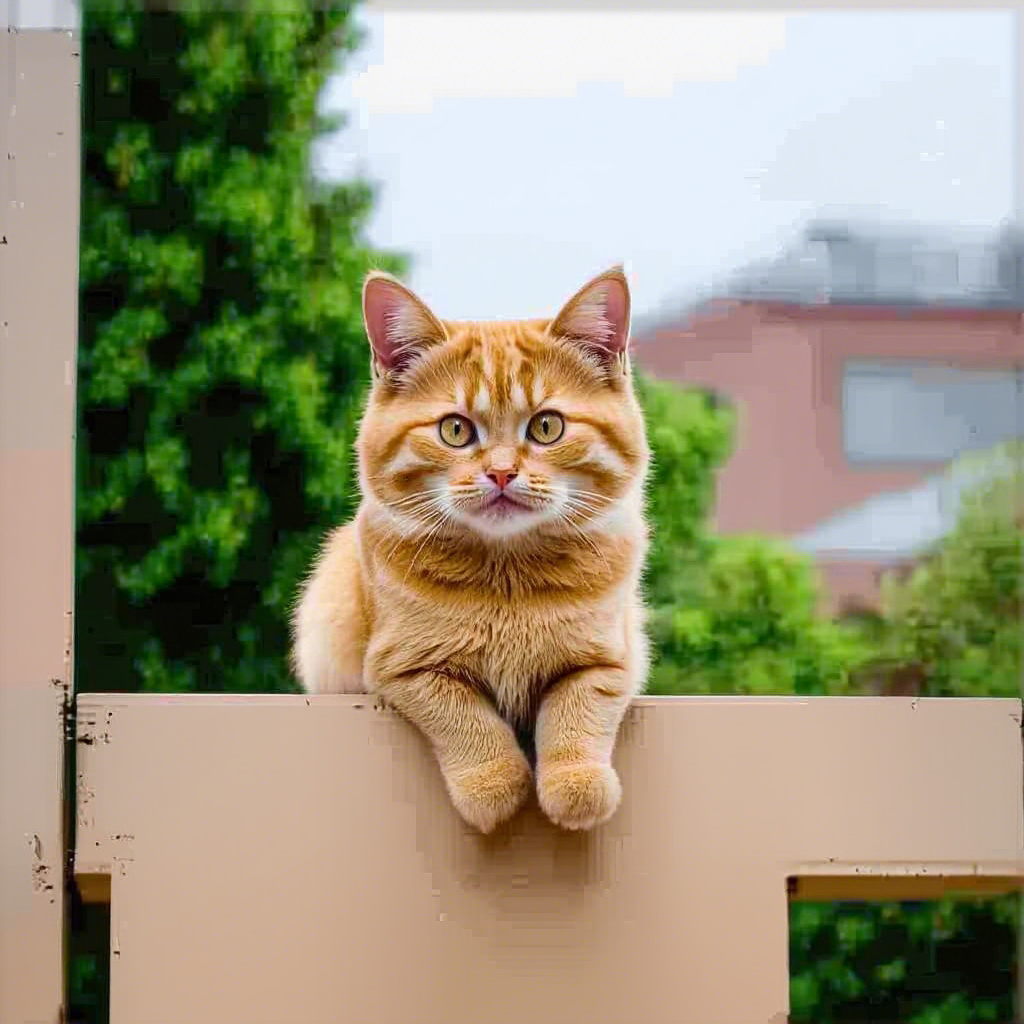
Reconstruction
ResNet50Real / AI-generated prediction
BLIP-2 first generates a caption for the image. I use that same caption during inversion and reconstruction with FLUX + FireFlow. This gives me the original image, an RGB representation of its inverted noise, and a reconstruction.
I combine the three RGB images into a nine-channel input for a modified, pretrained ResNet50. It learns to classify the input as real or AI-generated.
To test whether those extra inputs are useful, I also train an original-image-only ResNet50. Both use the same saved training, validation and test splits, with matching training settings.
Experiment setup
600 images from the Defactify Image Dataset: 300 real and 300 AI-generated.
420 training images, 90 validation images and 90 held-out test images.
Images resized to 224 × 224 for classification; aligned horizontal flips during training.
ImageNet-pretrained ResNet50, with selected convolution weights and the classification head trained.
Adam optimiser, learning rate 0.0001, batch size 8 and seed 42. Early stopping uses validation loss.
Accuracy, class-level precision and recall, F1, ROC-AUC, loss and Brier score used in evaluation.
September 2026 · Initial findings
A promising first comparison
Same 90 test images: 45 real and 45 AI-generated.
Input
Accuracy
ROC-AUC
Original + noise + reconstruction
87.78%
0.9516
Original image only
81.11%
0.9002
That is 79 correct classifications compared with 73 for the baseline. ROC-AUC measures how well the model separates the two classes across decision thresholds; higher is better.
The breakdown is more interesting than the headline accuracy. Both models detected 40 of the 45 AI-generated images. The difference was in real images: the baseline incorrectly labelled 12 as AI-generated, while my method labelled 6 that way.
Working through it
Research notes
Results, decisions and questions from the work so far. These entries look back at my saved experiments.
· Baseline comparison
What actually improved?
The method reached 87.78% accuracy. On its own, that number leaves a fairly obvious question: how well would the classifier do without the inversion?
The original-image baseline reached 81.11% on the same test images. Looking at the mistakes, both models caught the same number of AI images. My method made fewer mistakes on real ones. That gives me a more specific result to investigate than “the score went up”.
There are still only 90 images in this test set. Six additional correct predictions are encouraging, but I want to know how much of that difference survives another training run or a different set of images.
· Expanding the experiment
More data. How much is enough?
The first version used 200 images. This version uses 600, evenly split between real and AI-generated images. I’ve also made the experiment easier to trace, saving the image splits, predictions and training settings so the baseline can use the same setup.
I’m reporting several metrics because accuracy alone leaves too much out. But using the same metrics as another paper doesn’t automatically make the results comparable. A different dataset, classifier or test setup can change what those numbers mean.
For now, the most useful comparison is the one I can control: the original image alone versus the original, noise and reconstruction together. The larger dataset helps, but I still need to ask what it covers—and what it leaves out.
· First experiment
First, does it work at all?
Before choosing metrics or worrying about the size of the dataset, I needed to find out whether this adaptation could work at all. A technique being useful for image editing doesn’t mean its outputs will help a detector.
The first run used 200 images and correctly classified 25 of the 30 test images: 83.33%. That was enough to keep investigating. Without an original-image baseline, though, it couldn’t tell me how much the inversion was contributing.
I also think a negative result would be worth reporting. If the extra inputs don’t help under a clearly described setup, that tells us something useful. It wouldn’t prove the idea can never work, but it would help establish where it falls short.
Work I’m building on
FakeInversion — CVPR 2024. The detection approach I’m adapting.
FireFlow — ICML 2025. The inversion technique used in my pipeline.